Genz — traffic-camera event detection & accident anticipation
A two-part solution for the fixed-road-camera challenge: Part A detects and timestamps traffic events (accidents, near-misses, congestion, jaywalking, and more) in a finished video, and Part B watches a video frame-by-frame and outputs a causal, real-time accident-risk score that never looks at the future. Everything ships as a zero-training, zero-GPU, rule-based pipeline that runs on CPU out of the box, with an optional learned-detector upgrade path already wired in.
Team
Team Genz — three of us, roughly one core pipeline component each.
Sanjar Abduvaitov
Kamola Esheva
Sogdiana Erkabaeva
Problem & approach
The challenge has two parts, both over the same fixed, non-moving road-camera footage:
Part A -- event detection. Given a finished video, return every
interesting event as [start_sec, end_sec, label], where the label
is one of 14 fixed classes (accidents, near-misses, wrong-way driving,
jaywalking, congestion, and so on). This is scored after the fact, so the
whole video is available at once.
Part B -- accident anticipation. Given the same video played frame by frame, output a risk score from 0 to 1 at every frame, before anything bad has necessarily happened -- and it must be causal: at frame t the model may only use frames up to and including t, never later ones. The scoring rewards catching danger a few seconds early.
or optional YOLO
dominant flow direction
in order
rebuilt frame by frame
pedestrian signalscombined with max(), then
smoothed with EMA
src/detector.py also defines an optional
YoloDetector that swaps in automatically if the
ultralytics package and a weights/yolov8n.pt
file are both present -- a learned-detector upgrade path that's wired
but not required to run.
8 classes detected automatically
Each has a concrete, per-camera-agnostic signal derived from track geometry.
- stopped_vehicle — stationary ≥10s
- congestion — ≥3 vehicle tracks mostly stationary across the road for ≥8s
- wrong_way — heading ≥135° opposed to dominant flow
- near_miss — close approach + high closing speed, then divergence, no overlap
- accident — bounding-box overlap between two tracks
- road_obstacle — static "unknown"-class blob on the road for ≥10s
- jaywalking — person-classified blob inside the road-mask polygon
- failure_to_yield — vehicle–person bounding-box overlap
6 classes not yet implemented
Documented extension points — each needs per-camera calibration data (a calibration.json) we don't have without real sample footage. They never appear in detect_events output today.
- red_light — needs a calibrated signal-state ROI
- stop_line — needs a calibrated stop-line geometry
- illegal_u_turn — needs no-U-turn zone geometry
- illegal_turn — needs lane/turn geometry
- solid_line_crossing — needs lane-marking geometry
- fire_smoke — a MOG2 motion blob carries no reliable color/texture cue for smoke
EDA of sample videos
src/eda.py run against 2 of the 4 real
camera samples (C3896.MP4, C3897.MP4) --
the other 2 (C3902.MP4, C3905.MP4) weren't
re-analyzed before the deadline (they were already verified through
the full detection pipeline, see Results/Report; this section
specifically covers the lighter EDA pass). Numbers below are computed
directly from the video files, not invented.
Resolution / FPS / duration / object counts
| Video | Resolution | FPS | Duration | Mean vehicles | Mean people |
|---|---|---|---|---|---|
| C3896.MP4 | 3840×2160 | 29.97 | 340.3s | 6.50 | 0.96 |
| C3897.MP4 | 3840×2160 | 29.97 | 317.8s | 7.40 | 1.48 |
Mean counts are per-frame averages of MotionDetector's blob classifications, sampled every 0.5s across the full video (680 / 635 samples respectively) -- a coarse proxy for traffic volume, not a precise vehicle census.
Vehicle count over time (C3896.MP4)
Real per-frame vehicle counts from MotionDetector, sampled every 0.5s. The intersection is never empty and swings from roughly 1 to 11 concurrently-tracked vehicles as signal cycles queue and release traffic.
Motion heatmap — C3896.MP4
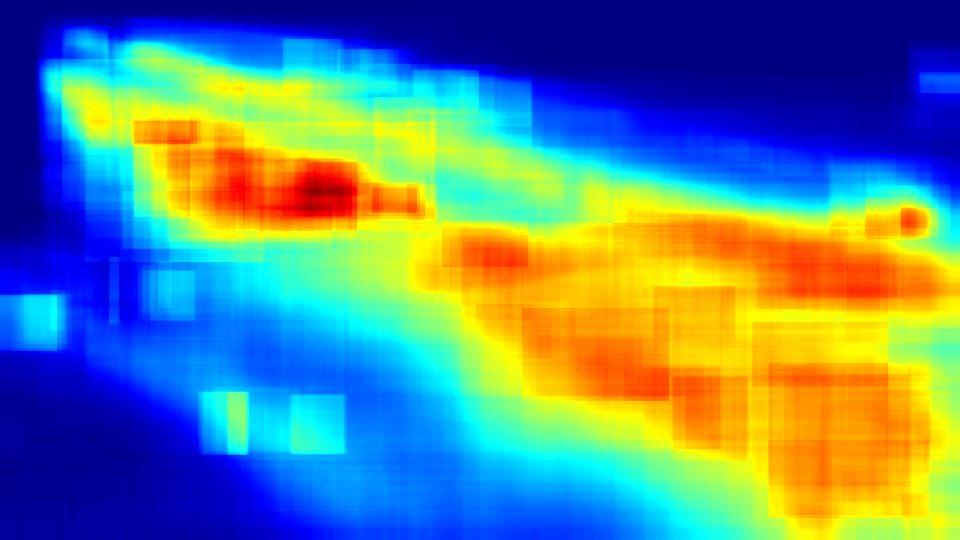
Real heatmap from accumulated detection boxes over the full video -- brighter regions are where vehicles/pedestrians were detected most often (the traffic lanes and crosswalk are clearly visible without any manual annotation).
Motion heatmap — C3897.MP4
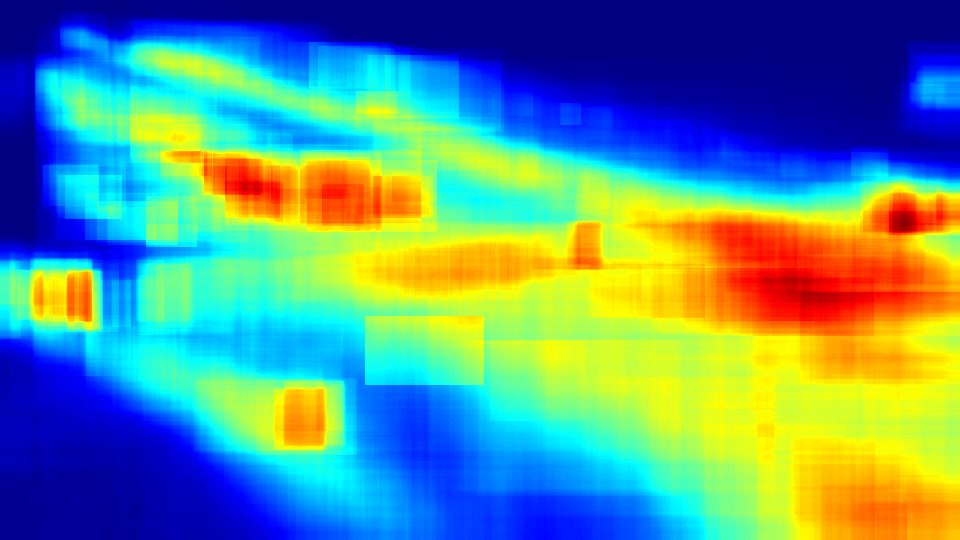
Same method, second video -- the lane structure and crosswalk again emerge directly from where motion was actually detected, with no manual ROI drawn.
Results on sample videos
samples/*.mp4 and have
been run through run_submission.py. The block below is a
synthetic mockup of the intended layout only.
sample_01.mp4 — event timeline + risk curve (synthetic example)
Live demo
Runs the real solution.detect_events() from this repo's
solution.py against a video you upload, live on this
server. This is a genuine model run, not a canned animation.
Limits: .mp4 only, up to 150 seconds (150s) and 200MB. Processing runs in the background, so a longer clip just takes longer to finish rather than timing out. Longer or larger files are rejected with an error rather than silently truncated. This demo currently shows Part A events only — risk-curve visualization: coming soon.
| Class | Start | End | Duration |
|---|
website/demo_server.py (a small
Flask app), publicly hosted at genzwiut.com
via cPanel's Python App (Passenger WSGI) on the team's own domain. You
can also run it yourself locally — see website/README.md
for the two commands. Opening this file directly from disk (rather
than via a server) will render the page fine, but the "Run" button
will fail to reach a backend, since there isn't one at a bare
file:// URL.
Report
What we built
- A zero-dependency motion detector (OpenCV MOG2 + contour classification) with an optional YOLOv8 swap-in when weights are present.
- A minimal greedy IoU multi-object tracker with full per-track position history.
- A self-calibrating road model (convex hull of observed vehicle positions + circular-mean dominant flow direction), usable both offline and causally.
- A rules engine that turns finished tracks into 8 of the 14 required event classes.
- A causal risk engine (Part B) combining time-to-collision, hard-braking, and pedestrian-proximity signals with max() + EMA smoothing, calibrated so a 5s time-to-collision maps to a 0.5 score.
- This website, including a working live-demo server, publicly hosted at genzwiut.com.
What worked
- The zero-dependency motion detector runs entirely on CPU with no training data and no GPU.
- The causal risk engine genuinely respects the no-future-frames rule:
RiskEstimator.step()only ever sees the current frame and its own running state. run_submission.py/evaluate.pymatch the challenge's own harness and metric spec (macro F1 across IoU 0.3/0.5/0.7 for Part A; AP + alarm-F1 + mean-time-to-accident for Part B;M = 0.7*ScoreA + 0.3*ScoreB) exactly, so scoring behaves as the organizers intend.
What didn't / limitations
- No labeled data exists yet, so every threshold (stationary speed, wrong-way angle, near-miss closing speed, etc.) is hand-picked from first principles, not tuned against real ground truth.
- 6 of 14 classes (red_light, stop_line, illegal_u_turn, illegal_turn, solid_line_crossing, fire_smoke) need per-camera calibration data we don't have and are left as documented extension points rather than guessed.
- Classifying "vehicle" vs. "person" from blob size/aspect ratio alone is weak and will misclassify unusual shapes; a real detector would help a lot — the YOLO hook is already wired for exactly this upgrade.
- accident / near_miss detection relies on 2D bounding-box overlap with no depth cue, so a vehicle that merely passes close to the camera's line of sight can look like an overlap and false-positive.
Next steps
- Get real sample videos into
samples/and generate real EDA and results. - Hand-annotate a small dev set and tune thresholds against
evaluate.pyinstead of by hand. - Drop in real YOLO weights (
weights/yolov8n.pt, seeweights/download.sh) for cleaner class labels. - Calibrate stop-line / signal-state ROIs / lane geometry per camera to unlock the remaining 6 classes.
Links
- Repository github.com/tordev1/Genz_eliminationtaskrepo
-
Live demo
genzwiut.com — this site, self-hosted on the team's own domain via cPanel's Python App (Passenger WSGI), running the repo's actual
solution.pypipeline. -
Model weights
The baseline ships with zero external weights (pure OpenCV + hand-written rules). An optional YOLOv8 weights file can be fetched with
weights/download.sh, but nothing in the default path requires it. - predictions_samples.json TODO Not generated yet — requires real sample videos (see EDA / Results above).